AI-POWERED CALL QA
CONTROLLED SCORING
No LLM scores your calls.
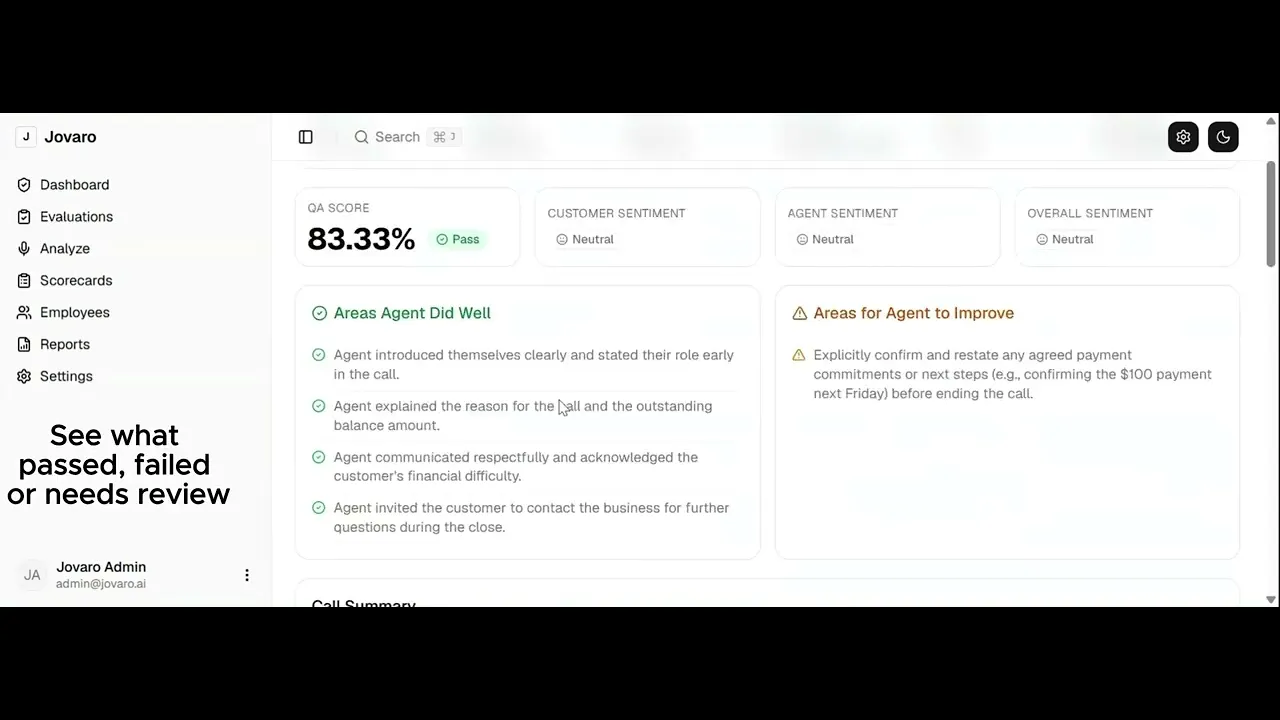
Your standards decide what a good call looks like. Every question on your scorecard gets an answer, your rules turn those answers into points, and a person sees anything the recording does not back up.
See how your calls score.
Run 1,000 minutes of calls through Jovaro AI and see the QA issues, compliance risks and review priorities it identifies.
Uses your existing QA standards · Human review stays in control · 1,000 audio minutes free
COMMON QUESTIONS
Scoring, plainly.
Does an AI score my calls?
No. Each rubric question is answered by a decision model — Jev, from TypeSafe AI — that returns a calibrated probability rather than text. Your scorecard rules convert those probabilities into points. No generative AI sets or writes a score.
Can the AI make things up?
It has nothing to make things up with. The scoring model returns a number, not sentences. A generative model is used only to quote the transcript as evidence, and it cannot return a verdict — its output schema has no field for one.
What if the evidence does not match the recording?
The question goes to human review. A pass only survives if its quoted evidence is found in the transcript. If it cannot be found, the question is routed to your review queue with a reason and an action, instead of being scored.
What if the model gets a call wrong?
It can. It is a model, not an oracle. That is why it never decides alone: its probability is compared against a fixed pass boundary, unsupported evidence becomes a review, and every result carries the threshold applied and the reason it was escalated.
Do you train AI on our calls?
No. Recordings are processed to produce your results and are not used to train any model.